Anthropic: how an agent remembers what matters, and what 'dreaming' adds
How does an AI agent learn from earlier sessions? In an engineering post on November 6, Anthropic describes memory in four layers: transcripts, notes Claude writes itself, representations such as a wiki, and context loaded into every session. An offline step Anthropic calls 'dreaming' checks those notes against the transcripts afterwards and fixes them. In Anthropic's tests, Claude Opus 5.5 with memory rose from 0.655 to 0.838 on the task benchmark CL-Bench.
If you work with agentic AI, the post is mostly practical: it shows which kind of memory helps when, and where it goes wrong. We explain the difference between memory and context in memory and context, the difference explained.
What Anthropic means by agent memory
The post is written by Lance Martin of the engineering team. Agent memory is knowledge Claude gains from experience, such as conversations and tasks, kept between sessions as text Claude can read later. Changing model weights, learning within a single conversation and summarising a long conversation (compaction) are excluded.
- Transcripts: a searchable log of what happened.
- Notes: written by Claude itself, during the work or in a memory directory.
- Representations: for example a wiki of linked pages about a subject.
- Injected context: what is loaded at the start of every session.
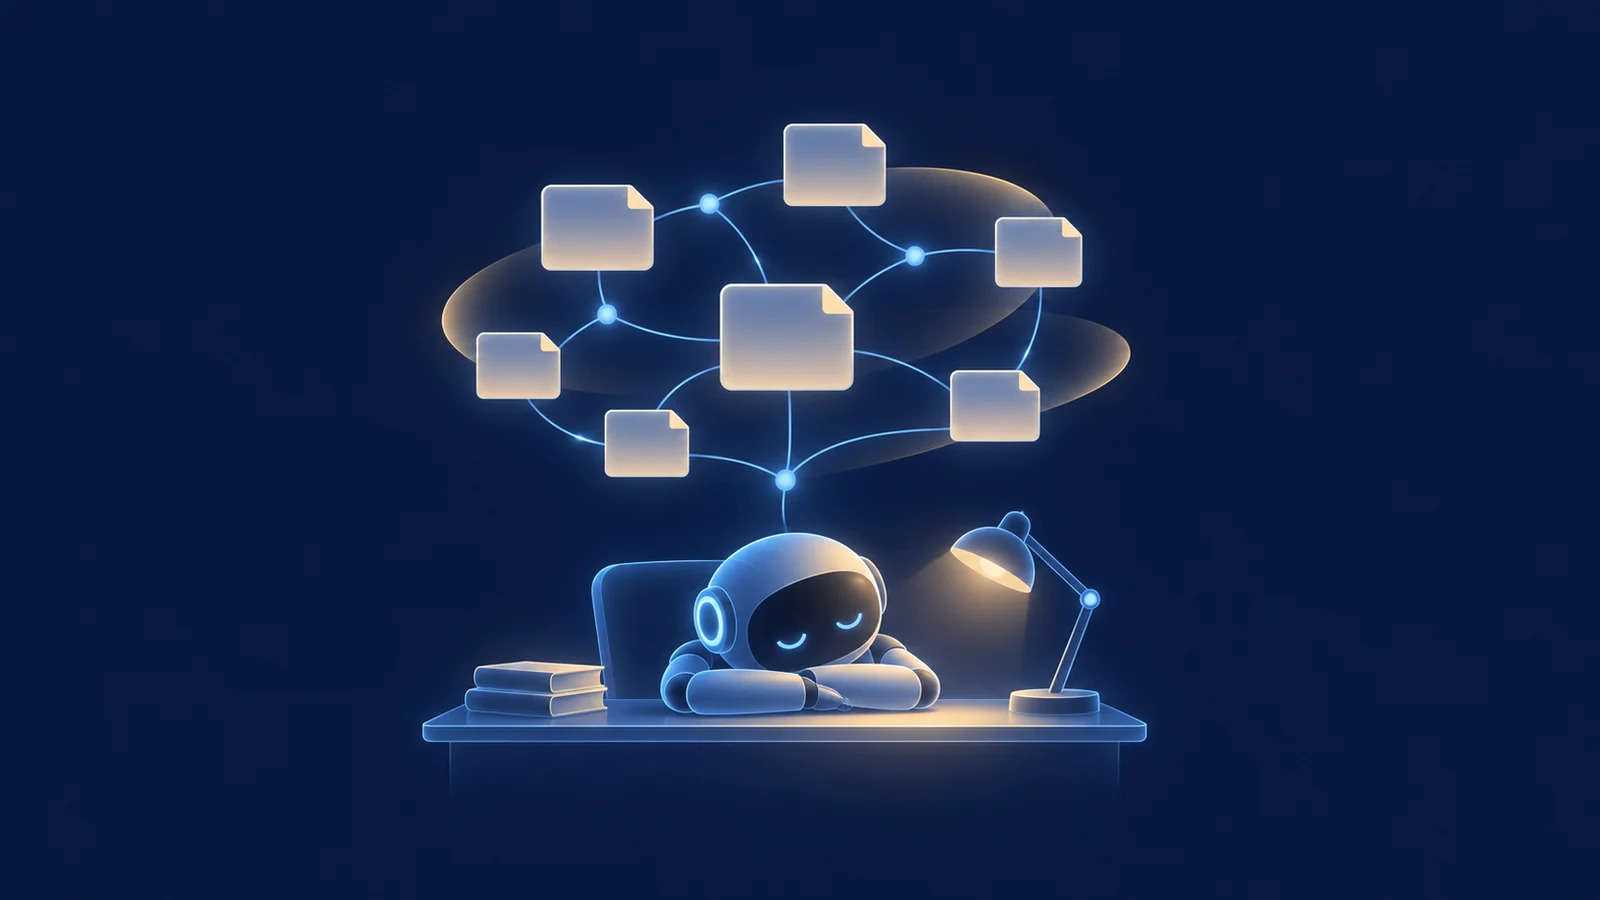
'Dreaming' connects these layers. Anthropic compares it to the way people consolidate experiences at rest and builds on the earlier 'sleep-time compute' idea from Letta and UC Berkeley. The post sums up the core problem: "For Claude to learn from experience, it has to decide what's worth remembering before it knows what's next."
The numbers from the tests
| Test | Without memory | With memory |
|---|---|---|
| CL-Bench 1.0, Claude Opus 5.5 | 0.655 | 0.838 |
| CL-Bench 1.0, Claude Sonnet 5.5 | 0.644 | 0.833 |
| CL-Bench 1.0, Claude Opus 4.7 | 0.383 | 0.700 |
| CL-Bench 1.0, Claude Sonnet 4.6 | 0.330 | 0.364 |
| Corpus of about 350,000 files (Stainless): wiki only | 13% | 48% after 128 sessions |
Two results stand out. Sonnet 4.6 barely benefited because it read its memory less than half the time; with a refined instruction it reached 0.641. And fixed rules about what to save can hold stronger models back: the instruction "record only failures" cost Opus 5 0.234 of its gain.
On that same corpus, search alone met 53% of the graded criteria and a wiki plus search 61%, using about 20,000 fewer tokens per question. On legal merger documents (the Harvey LAB benchmark) a wiki scored 87% against 73% for search on multi-document questions, but on another task the wiki showed no clear gain and grew to 1.77 times the size of its source.
One example of dreaming comes from a run in the game Pokémon Red: a note placed a building on the wrong side of a mountain. The dreaming step compared the note with the transcript and corrected it; the corrected run got further, the uncorrected run did not.
What you can do with it now
The post points to a memory directory and documentation on dreaming in Claude Managed Agents, and to the automatic memory in Claude Code. That loads only the first 200 lines or 25 KB of the MEMORY.md index at startup, and long instruction files lower adherence. If you maintain a CLAUDE.md or memory file, keep it short and put the most important rules at the top.
Anthropic names the limits itself: dreaming costs compute, a wrong note can carry into every later session, injected memory costs tokens and a wiki sometimes adds little over plain search. The signal also appeared in the briefing of November 7 and the Radar of November 7.
What we did not check
The numbers come from Anthropic's own tests; we could not reproduce them. CL-Bench is a benchmark Anthropic uses in the post; the post does not say which plans or API features already offer dreaming by default outside Managed Agents.
Checked on November 8, 2026.
This article was written with AI (Claude, Anthropic) and checked against the sources below. Because the post comes from Anthropic itself, llmnet.nl presents the numbers as the company's claims.
Sources
- Anthropic Engineering, The components of agent memory (Lance Martin, November 6, 2026): anthropic.com
- Announcement on X by @AnthropicAI: x.com/AnthropicAI